The Metered Mind: Putting Electricity on the AI Product Balance Sheet
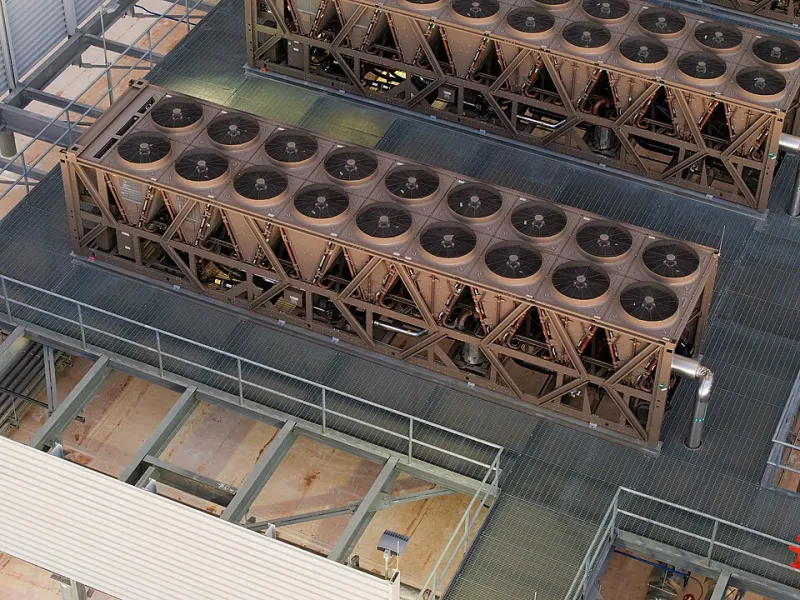
Photo: Rsparks3, CC0, via Wikimedia Commons
The constraint moves from silicon to the grid
For most of the generative AI boom, capacity conversations centered on GPUs. By 2026, the binding constraint has shifted. Data center operators face long interconnection queues, utilities are revising large-load tariffs, and some regions have paused new commitments while grid upgrades catch up. For product and engineering leaders, the implication is uncomfortable: the cost and availability of electricity now shape what AI features can be built, where they run, and what they cost to operate.
Most teams still model AI costs as token prices or cloud instance hours. That abstraction hides the physical layer. A feature that looks cheap per API call can be expensive once cooling, idle capacity, and demand charges are attributed to it. Conversely, a feature that seems expensive at list price may be perfectly viable if it can run in batches overnight or on a smaller model at the edge.
Measuring energy intensity per feature
The starting point is a per-feature energy estimate, however rough. At its simplest: energy per request equals compute energy plus memory and storage energy plus network energy, multiplied by the facility's power usage effectiveness, plus an allocation for idle capacity. For a retrieval-augmented generation feature, add the energy of embedding, vector search, and document storage. For an agentic workflow, multiply by the number of model calls and tool invocations per task.
Precision is less important than consistency. A team that measures the same way across features can compare them. A team that waits for perfect telemetry will never make a decision. Cloud providers increasingly expose carbon and energy estimates; colocation and on-premises environments require metering at the rack or node level.
The tariff trap
Electricity pricing for large loads is not a single rate. Demand charges, capacity tags, time-of-use rates, and contractual minimums can dominate the bill. A feature that runs inference at peak hours may incur a marginal cost several times higher than the same workload shifted to off-peak windows. In some US markets, capacity obligations are set by a customer's contribution to peak demand, which means a latency-sensitive feature that keeps GPUs hot all day can raise costs across the entire facility.
Product leaders do not need to become utility experts, but they do need to ask where their workloads land on the load curve. Batch pipelines, asynchronous summaries, and overnight indexing are friendlier to the grid than interactive chat that must respond in milliseconds. Designing for temporal flexibility is a cost strategy as much as a sustainability one.
Power-aware SLAs and vendor negotiations
As energy becomes a constraint, contracts should reflect it. Enterprises can ask infrastructure providers for energy reporting at the workload level, commitments around renewable procurement, and clarity on how curtailment or grid events will be handled. For AI platform vendors, ask whether pricing includes energy pass-throughs and how rate changes are communicated.
Power-aware service-level agreements are still immature, but the direction is clear. A provider that cannot say how much energy a workload consumes, or how it behaves when the grid is stressed, is a provider whose costs will be opaque.
When smaller models and edge inference win
The energy math often favors smaller models. A distilled or quantized model running on a modest accelerator can handle classification, extraction, and routing tasks at a fraction of the energy of a frontier model. Edge inference — on a laptop, a phone, or a gateway device — can eliminate network and data center overhead entirely for some workloads, while also addressing latency and data residency concerns.
The decision is not ideological. It is a function of task complexity, latency tolerance, data sensitivity, volume, and the marginal cost of energy at the point of execution. A feature that runs a million times a day at the edge has a different energy profile from one that runs a thousand times a day in a centralized cluster.
A decision framework for product leaders
Before committing to a centralized model, ask: Can the task be handled by a smaller model with acceptable quality? Can it tolerate batch or off-peak execution? Does it require data to leave the device? What is the energy cost per successful task, not per API call? And what happens to unit economics if electricity prices rise or capacity is curtailed?
The answers will not always point away from the cloud. But they will make the trade-offs visible. In 2026, the power bill is no longer a facilities concern that arrives after the product ships. It is a design input, and the teams that treat it as one will have more room to build when the grid is tight.